A fine-tuned Vision-Language-Action (VLA) policy can easily place the alphabet soup in the basket on command, just as it saw during fine-tuning. However, if the basket is shifted five centimeters to the left, it drops the soup off the table. We developed an interpretability pipeline to investigate what such a policy is computing. Injecting task A's activations into the action expert while the policy looks at task B's scene makes π0.5 execute task A's motor trajectory in 99.6% of episodes (n = 1,968). The injected program is bound to absolute workspace coordinates and ignores the visible scene, which provides a mechanistic account of the perturbation brittleness that concurrent benchmarks report. The binding holds on a physical UR10e: directed replay redirects the commanded task in 26/26 rollouts in one direction and 18/26 in the other, with no-injection and random-direction controls at the floor, and once the source object is moved 10–15 cm the arm grasps and releases at the recorded coordinates in 50/50 trials, picking up the wrong block when one sits there and closing on empty air when none does. Applying the same interventions to six VLAs (π0.5, OpenVLA-OFT, X-VLA, SmolVLA, GR00T N1.5, and ACT as a language-free control) on LIBERO, MetaWorld, SimplerEnv, and ALOHA over 420,000+ rollouts yields three further findings: every architecture encodes the instruction yet weights it far below vision whenever the scene alone identifies the goal; the SAE pooling that preserves behavior is architecture-specific (π0.5 per-token, X-VLA mean-pool, SmolVLA indifferent); and goal selection and motor generation separate into VLM and expert pathways wherever the two are distinguishable. The effect is not universal: SmolVLA's interleaved fusion lowers the override to 52.1% on LIBERO. We release Action Atlas, an interactive platform covering all 520+ trained SAEs, 79 identified concepts, and the scored UR10e rollouts.
Per-token Sparse Autoencoders + causal interventions for VLA mechanistic interpretability
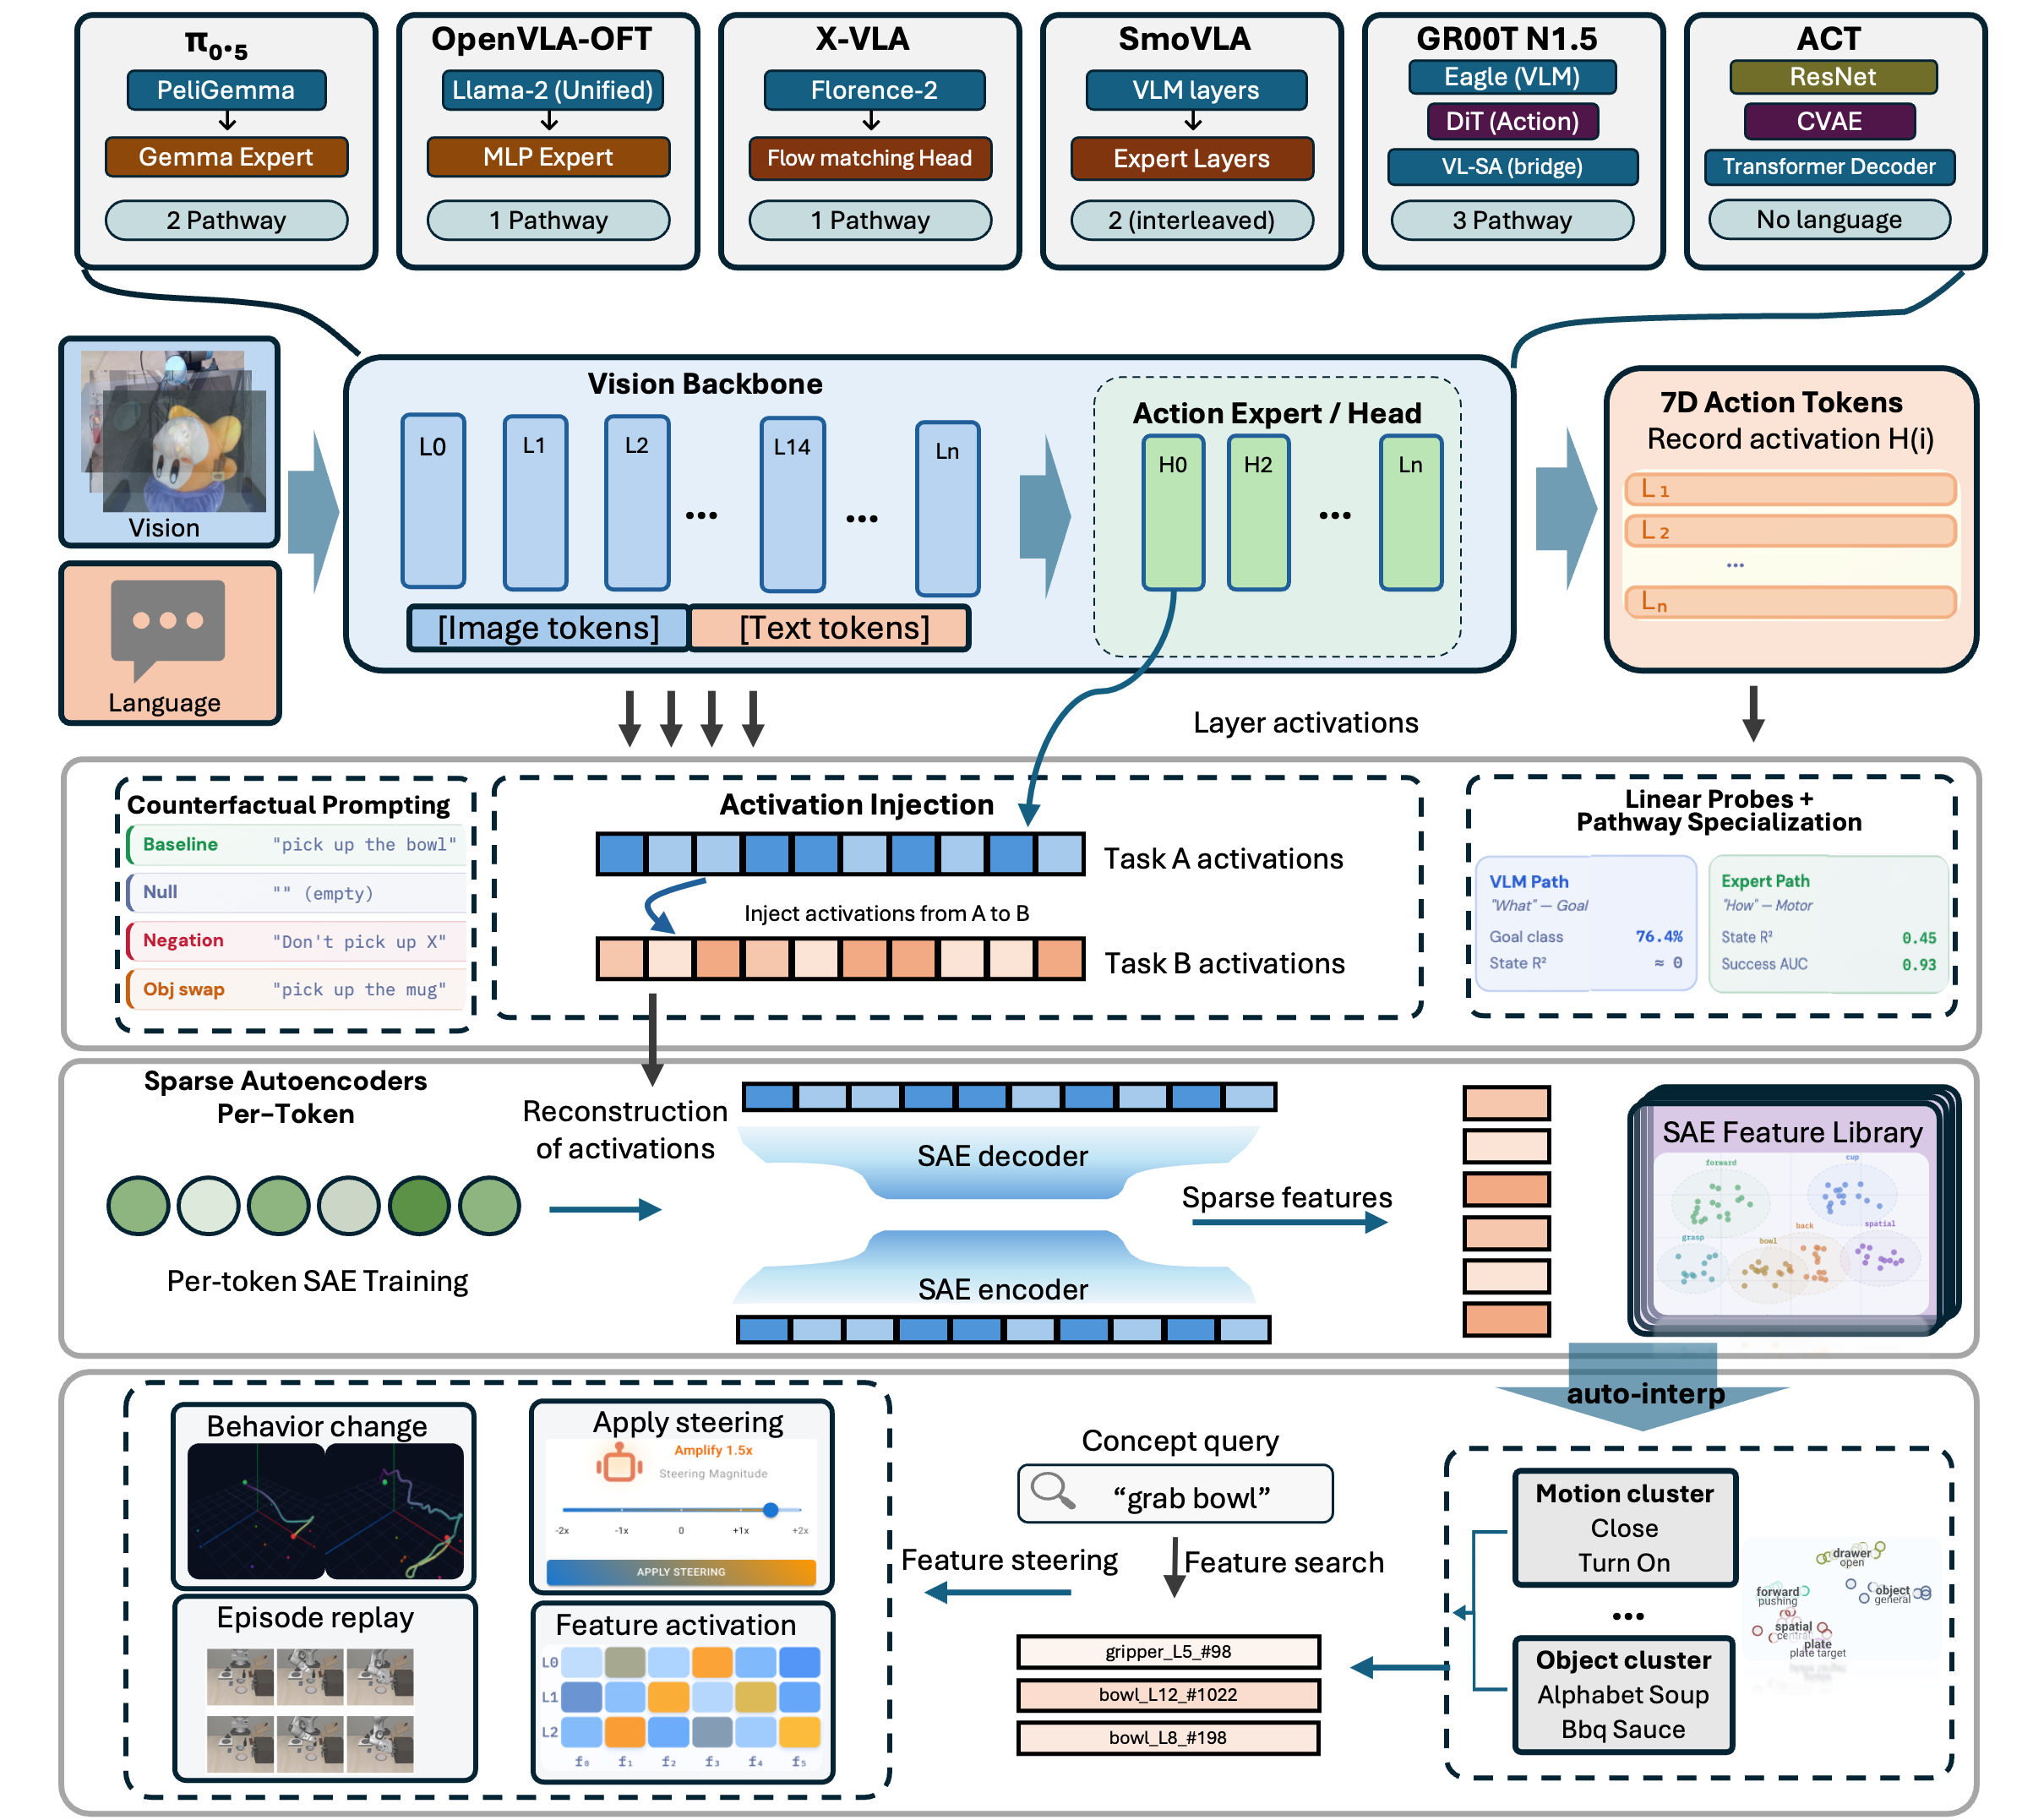
Methodology overview. Top: activations are recorded from VLA backbone and action expert layers during rollout episodes, then replayed under counterfactual conditions (null prompts, cross-task scenes) to establish causal relationships via behavioral change. Middle: per-token SAEs decompose layer activations into sparse features. Bottom: features are clustered, searched, and causally validated through ablation and steering experiments, with results visualized in Action Atlas.
We train 520+ TopK SAEs (k=64) across all six models with 4–8× expansion. Each action token is processed independently to preserve temporal structure. Feature importance is scored via frequency-weighted contrastive selection (Cohen's d × top-k frequency), recovering 79 aligned manipulation concepts.
We test causality with four injection conditions: null injection (correct prompt to empty string), same-scene steering (redirect to alternate targets), cross-task injection (transfer across visual scenes), and random-direction (norm-matched control: 22% source behavior at n=50 and 45.5% override at n=200, against 99.6% directed).
Concept ablation zeros out specific SAE features during live rollouts, while feature steering scales feature activations by α to amplify or suppress encoded behaviors.
Ridge regression probes recover prompt-category labels at > 99% accuracy from the residual stream of every model tested. A projection operator test confirms causality: projecting out the probe direction drops downstream R² to chance.
We test language grounding with 6 prompt variations across all five language-capable VLAs: baseline, null (empty string), negation, motor commands, object swap, and mid-episode temporal switches, at up to 500 episodes per cell (π0.5 and SmolVLA on LIBERO). SmolVLA is additionally evaluated across MetaWorld's four difficulty tiers.
A six-step argument across six VLA architectures, in simulation and on hardware
Replacing the prompt with an empty string and replaying the image stream from a different episode restores actions to cosine ≥ 0.99 against the original, with rollout success recovering to 14–80% on π0.5 and OpenVLA-OFT. Zeroing any single layer sends X-VLA and GR00T-DiT to 0%, while SmolVLA tolerates single expert-layer zeroing.
Cross-task injection rebinds the trajectory, not the goal. Tie-inclusive override, labeled per metric: π0.5 99.6% (n=1,968, action cosine), OpenVLA-OFT 77.9% (n=1,079, action cosine; 96.4% tie-conditional), X-VLA 52.8% (n=2,907, end-effector velocity; 99.8% tie-conditional under action cosine), SmolVLA 52.1% (n=720), GR00T 6.7% (n=180, end-effector velocity; 57.0% action cosine). A norm-matched random direction gives chance-level override (45.5%, n=200), and the vision-only ACT control produces 0.0% by construction.
Linear probes recover prompt-category labels at > 99% accuracy: the instruction is encoded. Its behavioral weight depends on the scene: with an empty prompt π0.5 keeps 31.6% success on LIBERO-Object and 5.8% on LIBERO-Goal (n=500 per cell, baselines 91.0% and 92.6%), a 5.4× gap between the visually unambiguous and ambiguous suites; told not to do the task, it does it in 96.7% of episodes. OpenVLA-OFT keeps 96% under a null prompt on Object and 12% on Goal.
Quantified on SmolVLA and reproduced directionally on π0.5 and GR00T: expert pathways carry the motor program and VLM pathways carry the goal. SmolVLA's expert accounts for 78.6% of cross-task override against 25.6% for the VLM, and its expert activations decode ground-truth state at 4.5× the VLM rate; on π0.5 the VLM side decodes the goal better (76.4% vs. 62.6%).
π0.5 fine-tuned on a UR10e over seven tabletop tasks, same wholesale expert replay at L16/L17 between plushie-in-bowl and gray-on-blue stacking. Directed injection redirects the commanded task in 26/26 rollouts in one direction and 18/26 in the other, against matched-scene floors of 0/24 and 0/25 and a norm-matched random direction at 0/25 and 1/23. With the source object moved 10–15 cm, the injected program drives the arm to the recorded coordinates in 50/50 trials while the uninjected policy reaches the displaced object.
Which pooling preserves rollout fidelity is an architectural property, not a universal VLA property: per-token preserves π0.5 and OpenVLA-OFT, mean-pool suits X-VLA, and SmolVLA is indifferent. Single-feature SAE ablation produces 28–92% zero-effect rates depending on architecture, and causal sensitivity does not follow representation width.
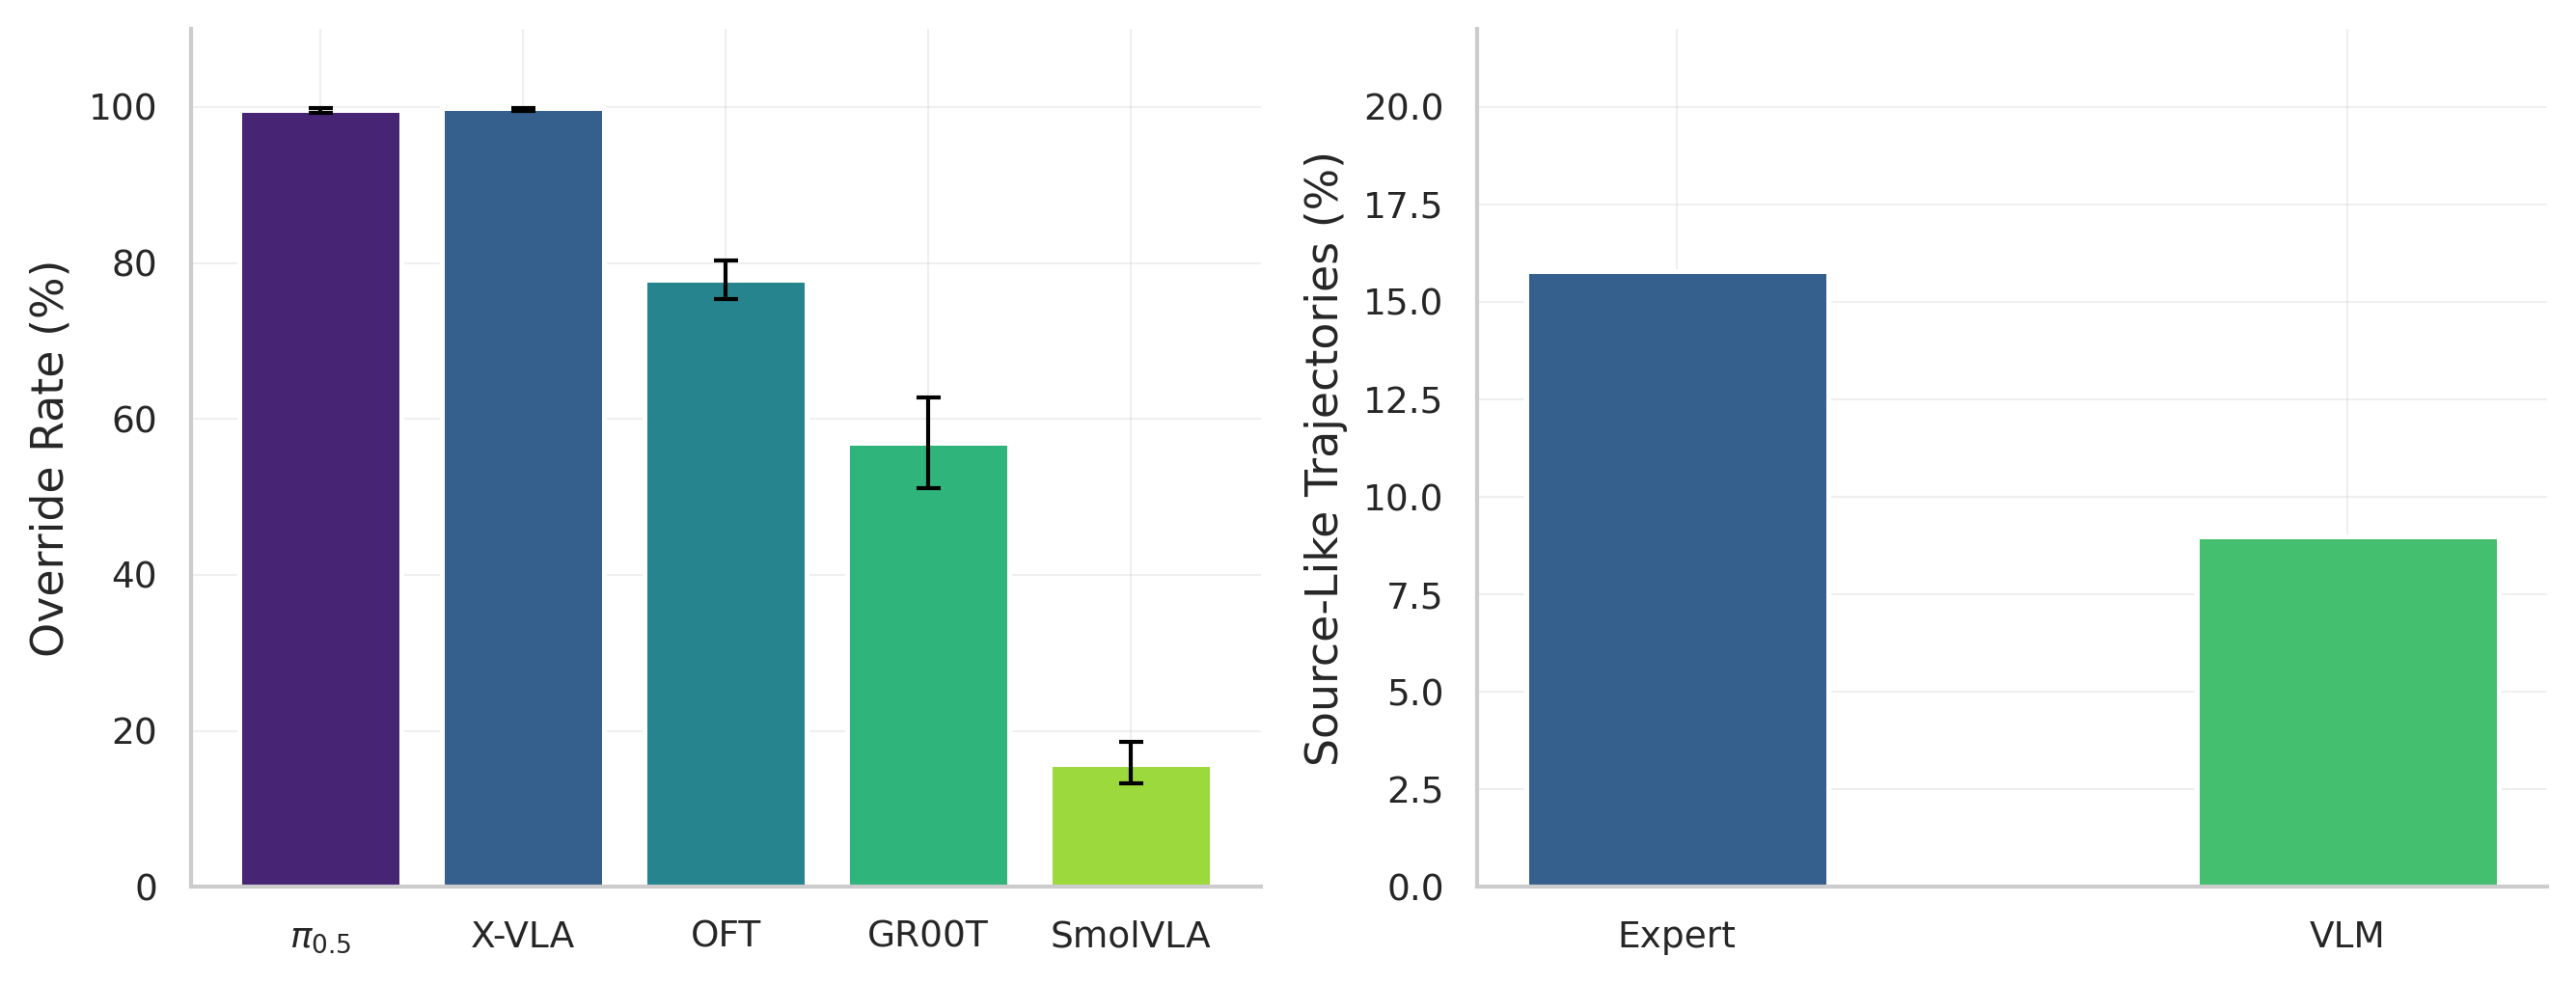
Cross-task injection override rates, tie-band-conditional under action-vector cosine: π0.5 99.6% (n=1,968), X-VLA 99.8% (n=3,150), OpenVLA-OFT 96.4% (n=1,079), GR00T 57.0% (n=270). Tie-band fractions differ sharply across models, so the conditional rates are not directly comparable; tie-inclusive rates per metric are in the paper. Right: SmolVLA pathway split on LIBERO, 78.6% expert vs. 25.6% VLM (n=720).
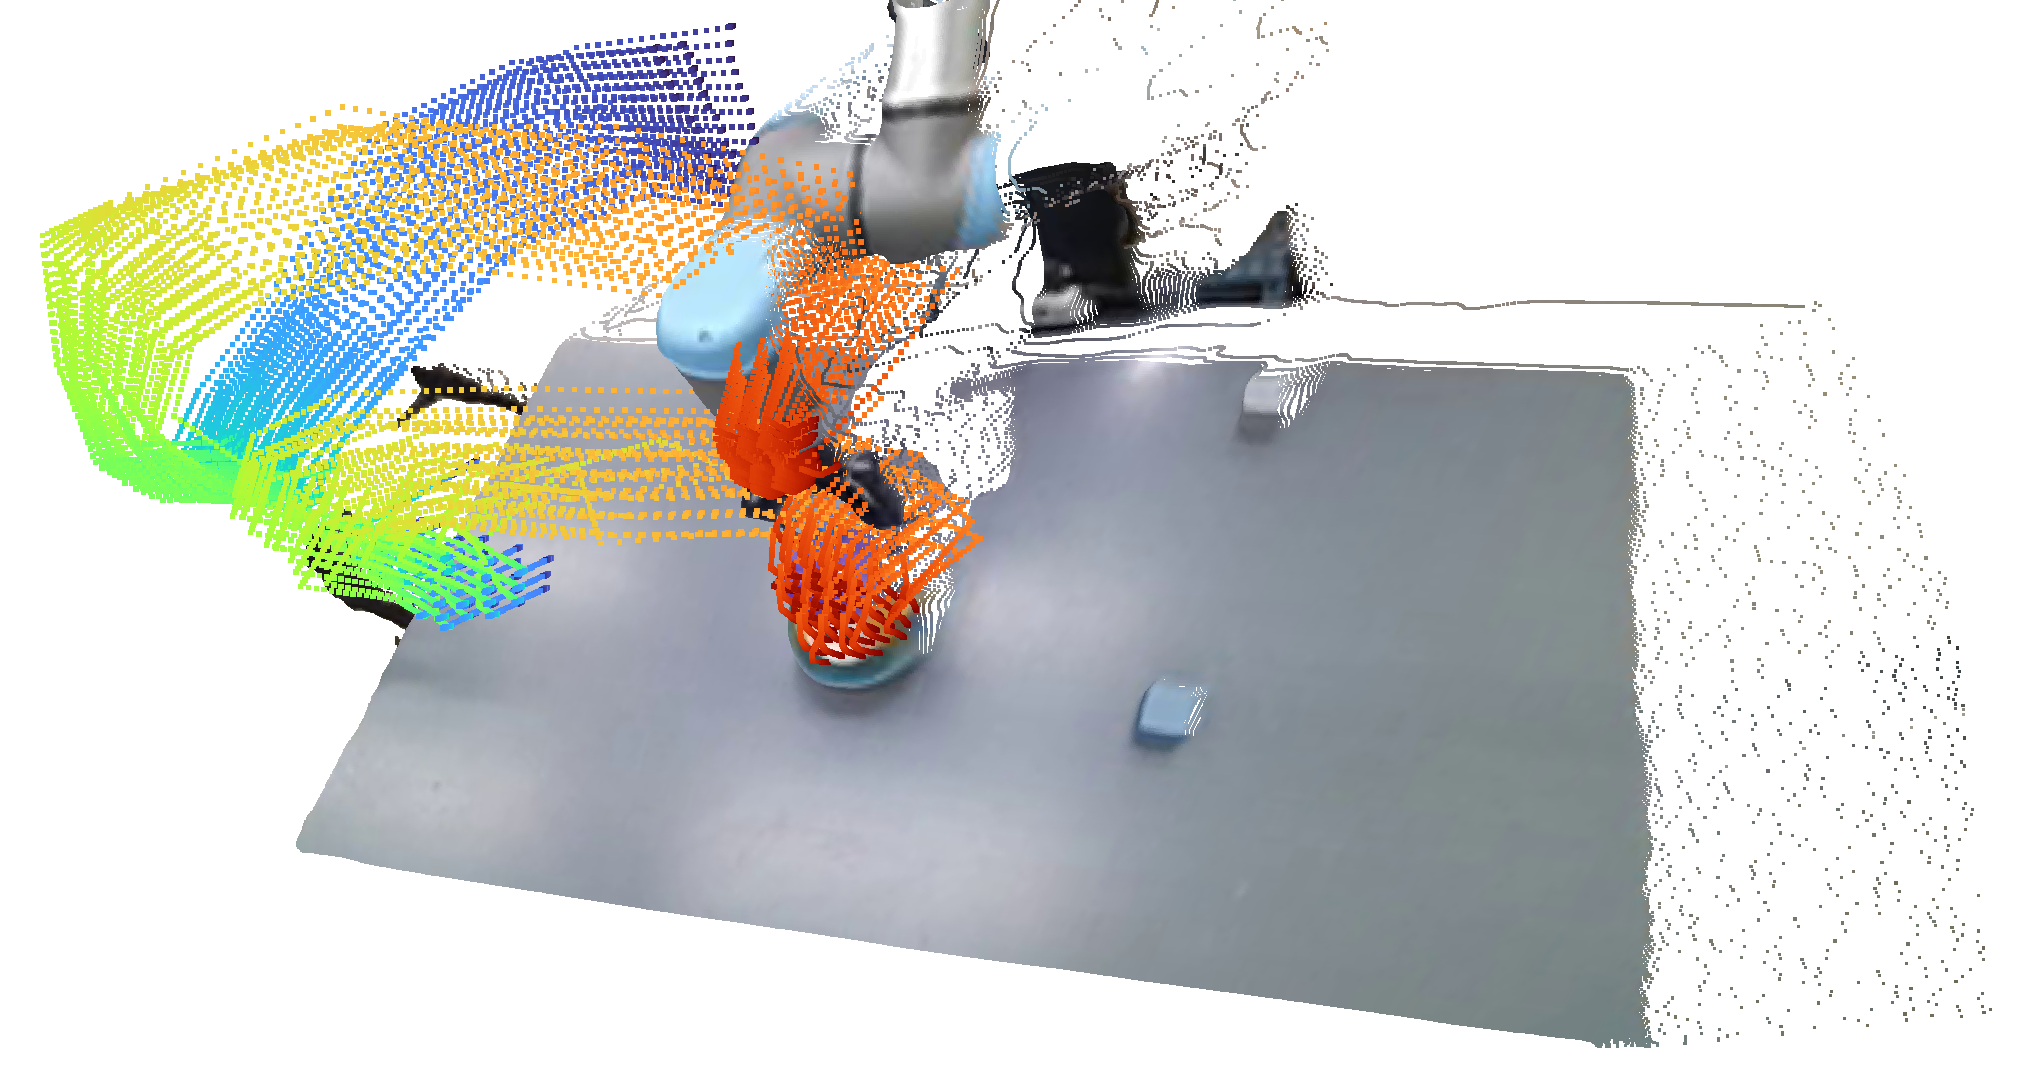
Directed injection on the UR10e. Plushie program injected at expert L16/L17 under the prompt to stack the blocks: the arm leaves the home pose, reaches the plushie, and carries it to the bowl while the blocks stay untouched. Tracked points colored from start (blue) to end (red) over a metric-depth reconstruction of the workspace.
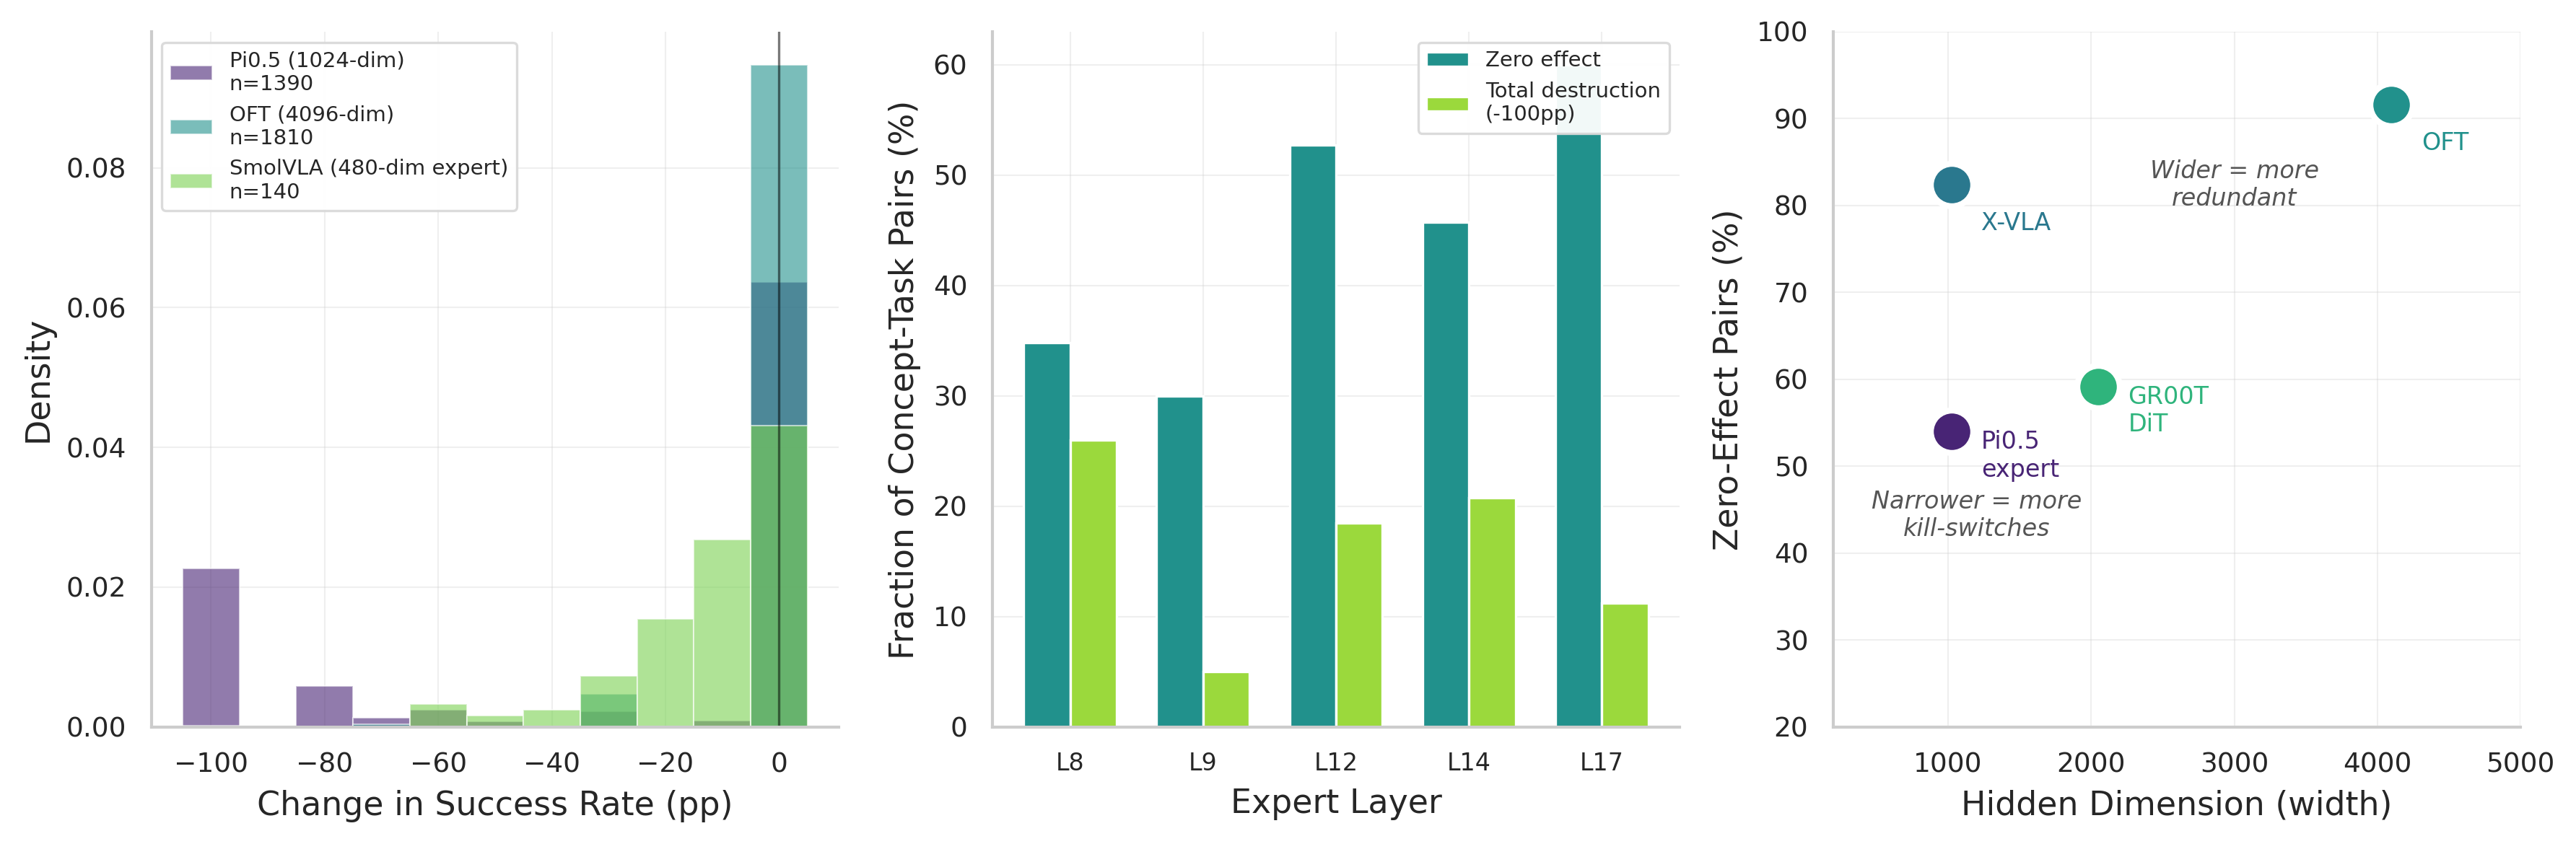
Single-feature concept ablation across five language-capable VLAs. SmolVLA (480-dim expert) is the most sensitive at 28% zero-effect rate; OpenVLA-OFT (4096-dim) and X-VLA (1024-dim) are the most resilient at 92% and 82%. Causal sensitivity does not follow representation width; it is architecture-tied.
| Model | Hidden Dim | Zero-Effect Rate | Destruction Rate | Profile |
|---|---|---|---|---|
| SmolVLA Expert | 480 | 28% | 6.3% | Narrow, most sensitive |
| π0.5 Expert | 1024 | 54% | 14% | Bimodal, kill-switches at L8 |
| GR00T N1.5 | 1536-2048 | 59% | 9.1% | Pathway-dependent (DiT > Eagle) |
| X-VLA | 1024 | 82% | 2.7% | Resilient despite narrow width |
| OpenVLA-OFT | 4096 | 92% | 0.5% | Wide, most resilient |
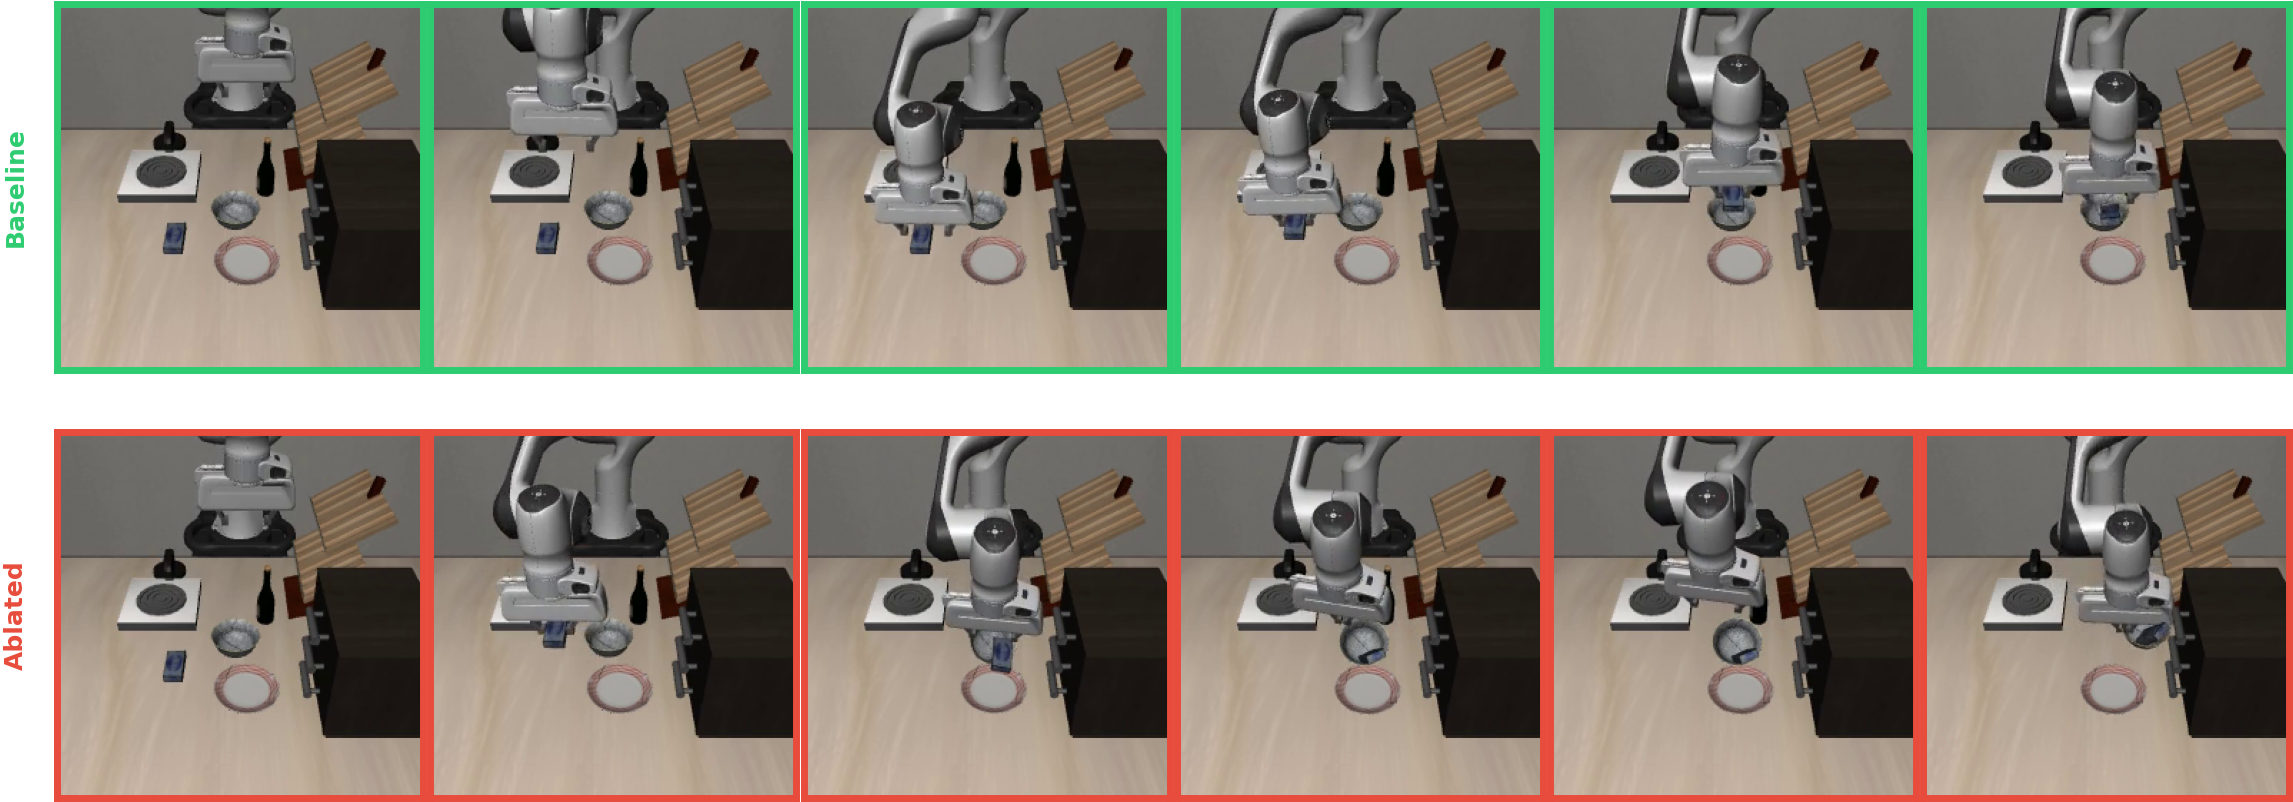
PUT concept ablation (L8): “Put the cream cheese in the bowl.” Top: baseline picks up cream cheese and places it in the bowl (91 steps). Bottom: with PUT features zeroed, the robot drops the cream cheese into the bowl, knocking it over (300 steps, task failure).
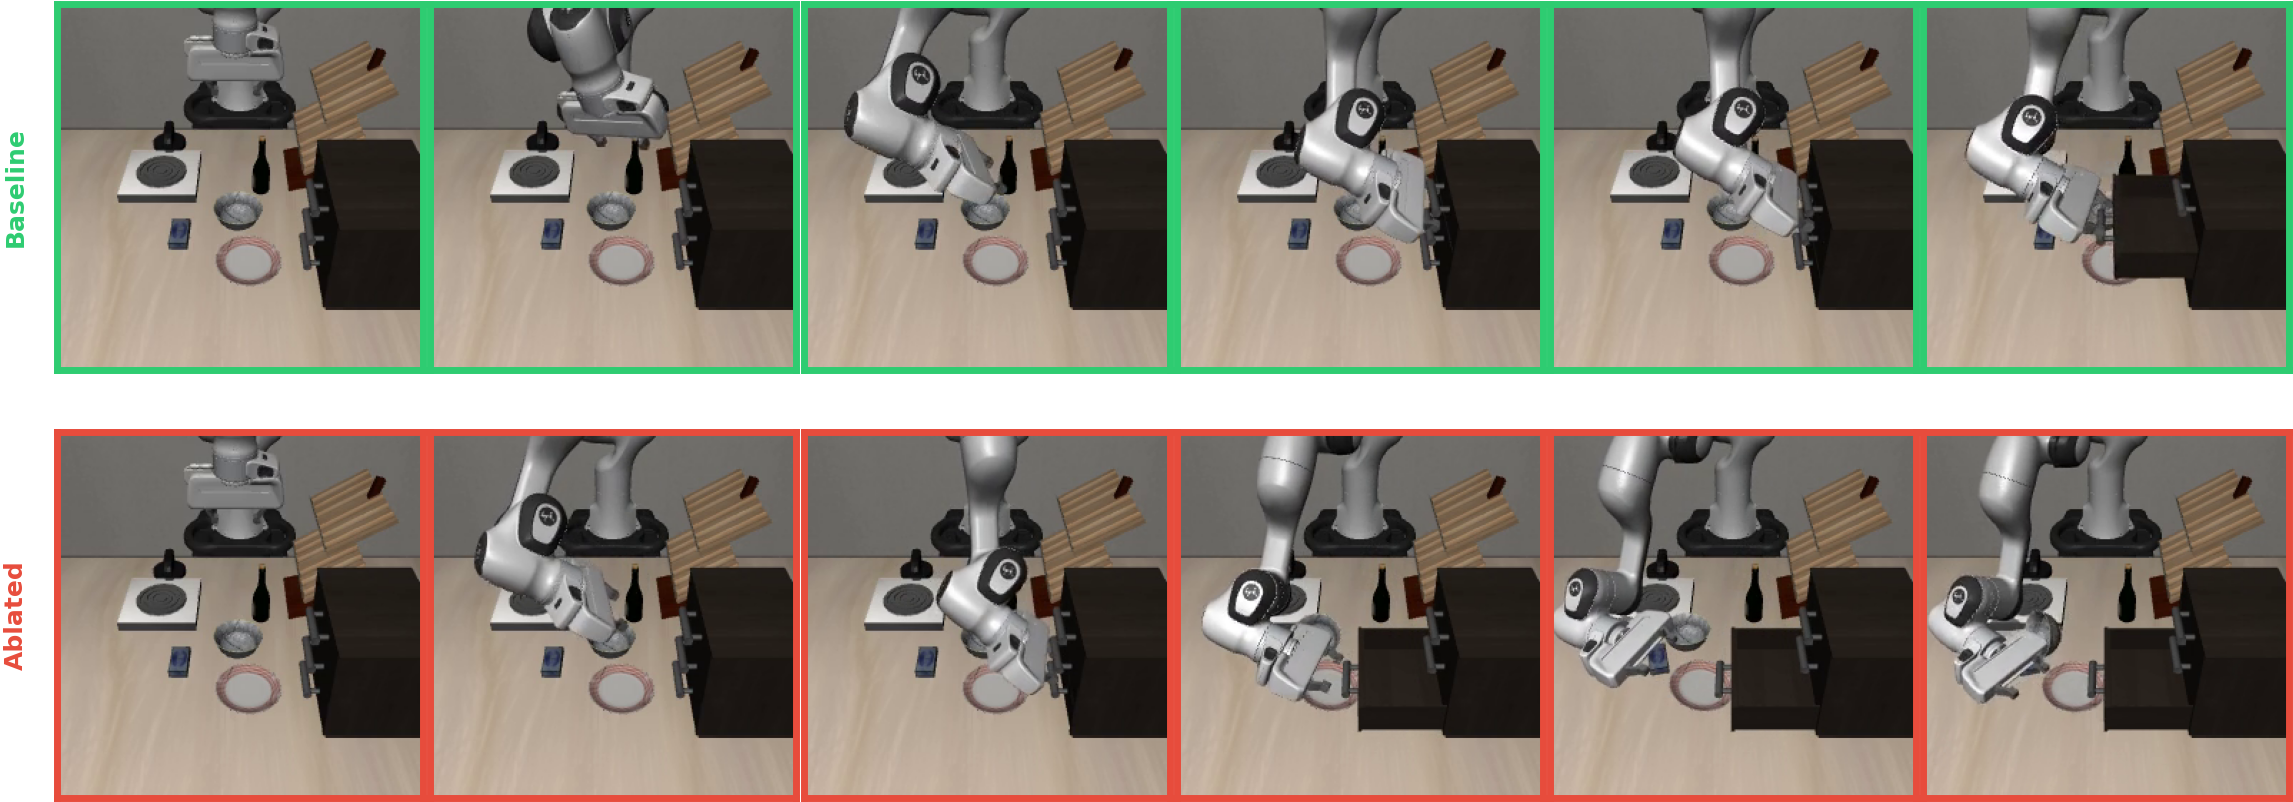
OPEN concept ablation (L8): “Open the middle drawer of the cabinet.” Top: baseline reaches for the middle drawer, grasps and pulls it open (140 steps). Bottom: with OPEN features zeroed, the robot opens the bottom drawer instead of the middle, misdirecting the motor program to the wrong target (300 steps, task failure).
Five VLAs and one language-free control, 80M to 7B parameters, three action generation paradigms
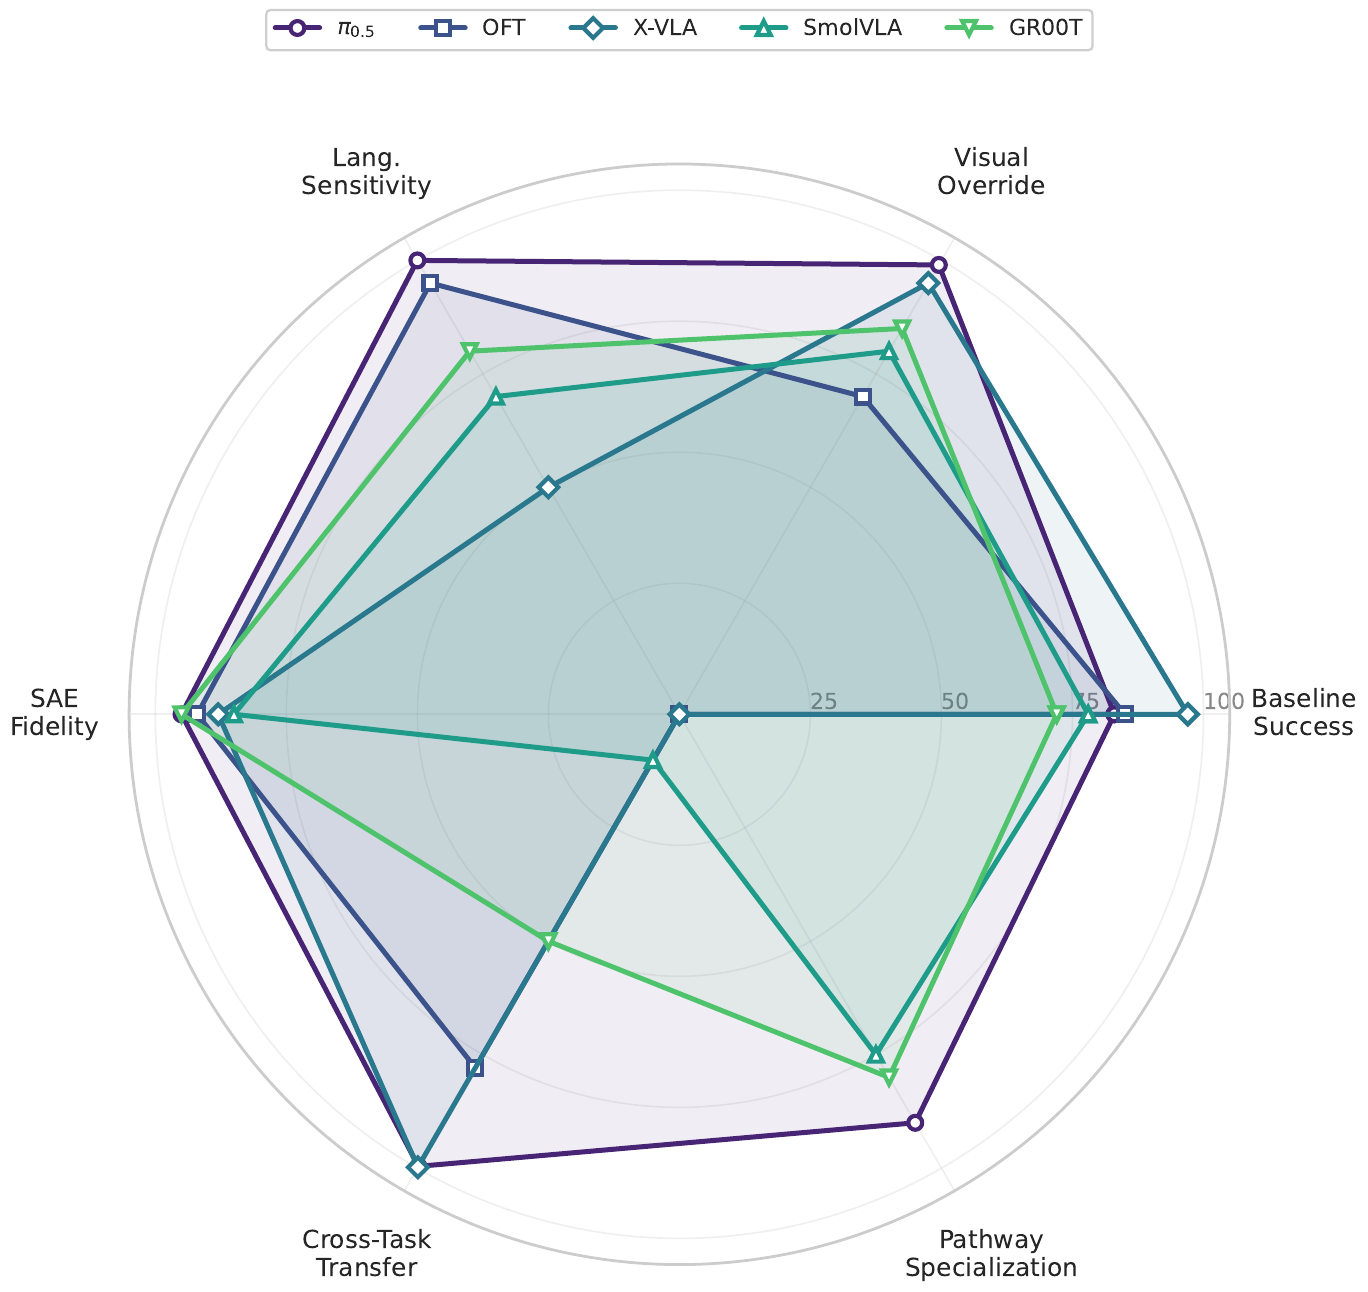
Cross-model capability radar, each axis a linear map of one table in the paper: baseline success, visual override (destination success lost under injection), language tolerance (null-prompt over correct-prompt success), SAE fidelity (best-arm rollout success), cross-task transfer (tie-inclusive override), and ablation tolerance (zero-effect rate of single-feature ablation).
4 suites, 40 tasks
MuJoCo tabletop
10 tasks, 2 embodiments
WidowX + Google Robot
Bimanual tasks
TransferCube, Insertion
50 manipulation tasks
Multi-task evaluation
| Model | Episodes | SAEs Trained | Concepts ID'd | Benchmark(s) |
|---|---|---|---|---|
| π0.5 | 71,500+ | 72 | 46 | LIBERO |
| OpenVLA-OFT | 70,700+ | 96 | 45 | LIBERO |
| X-VLA | 74,500+ | 120 | 55 | LIBERO, SimplerEnv |
| SmolVLA | 58,000+ | 146 | 60 | LIBERO, MetaWorld |
| GR00T N1.5 | 164,700+ | 87 | 39 | LIBERO |
| ACT | 1,870 | - | - | ALOHA |
| Total | 420,000+ | 520+ | 79 unique | 4 benchmarks |
Interactive visualization platform for VLA interpretability, inspired by Neuronpedia
UMAP scatter plots of 4,096+ SAE features with semantic search via SBERT embeddings
Architecture diagrams showing information flow and concept density across transformer layers
308,000+ rollout videos filterable by model, suite, experiment type, and outcome
Side-by-side baseline vs. ablated behavior with success comparison
Vision perturbation results across models with displacement analysis and cross-embodiment data
action-atlas.com
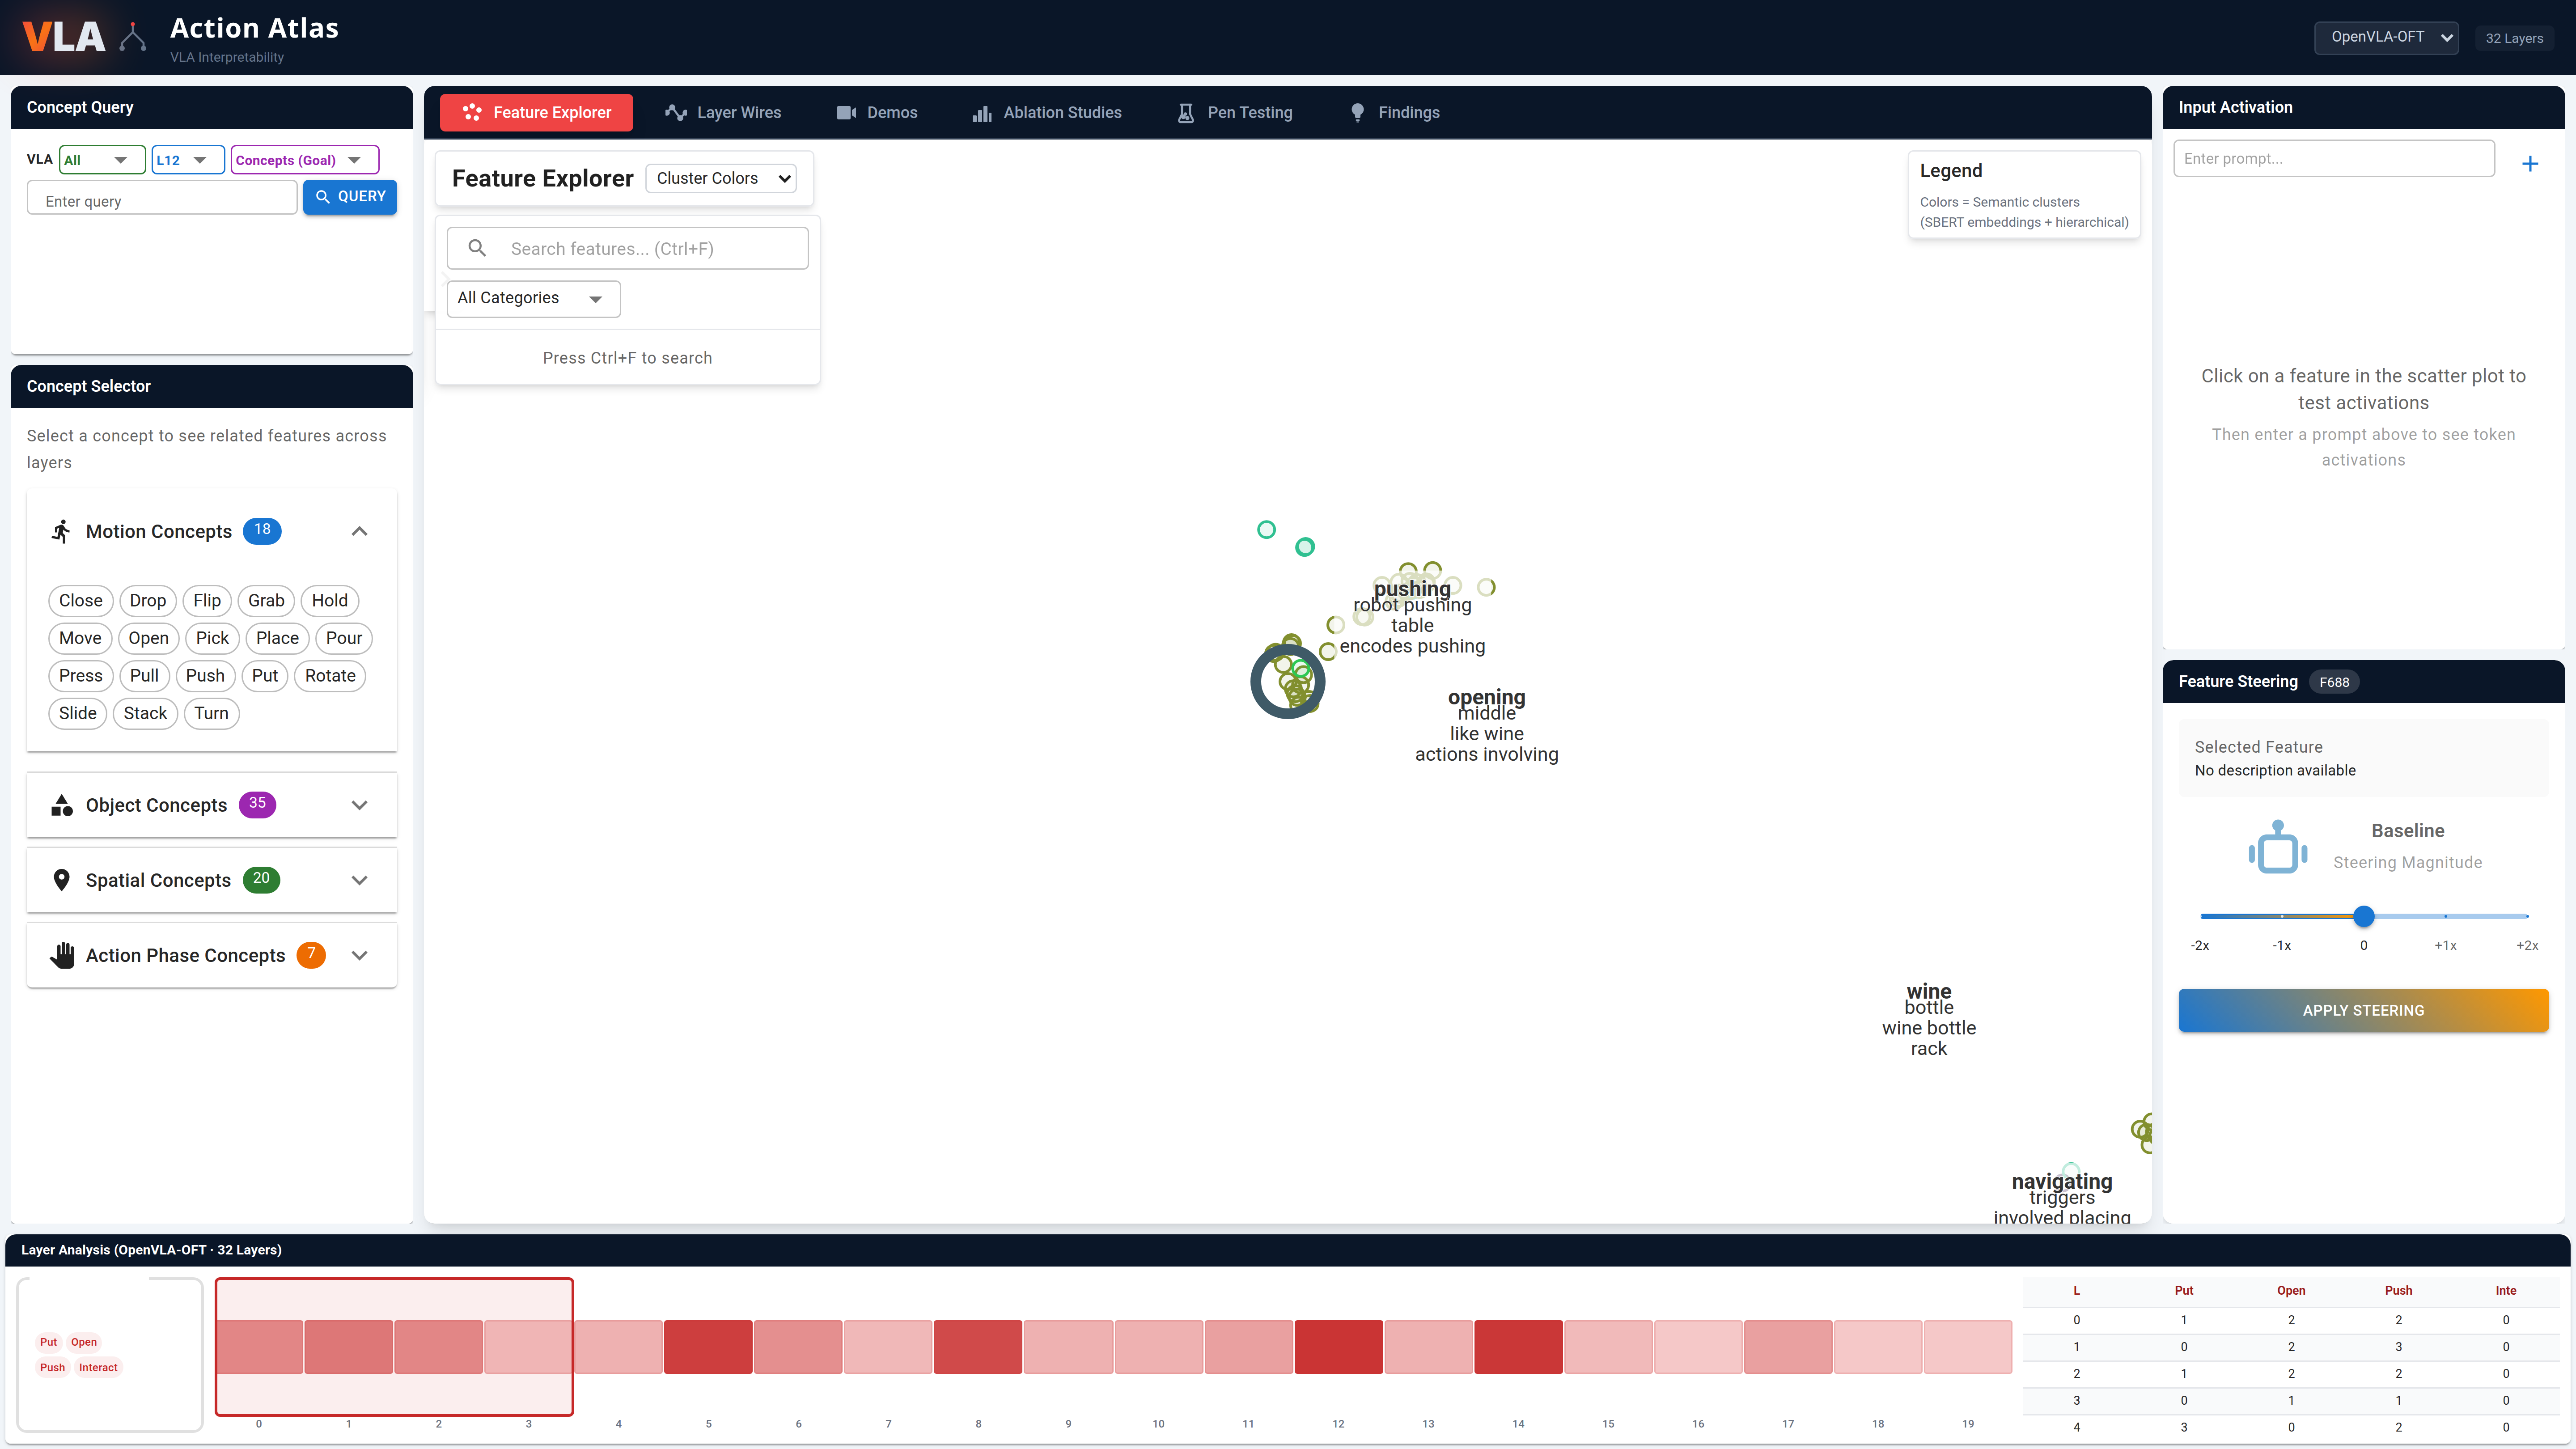
Feature Explorer
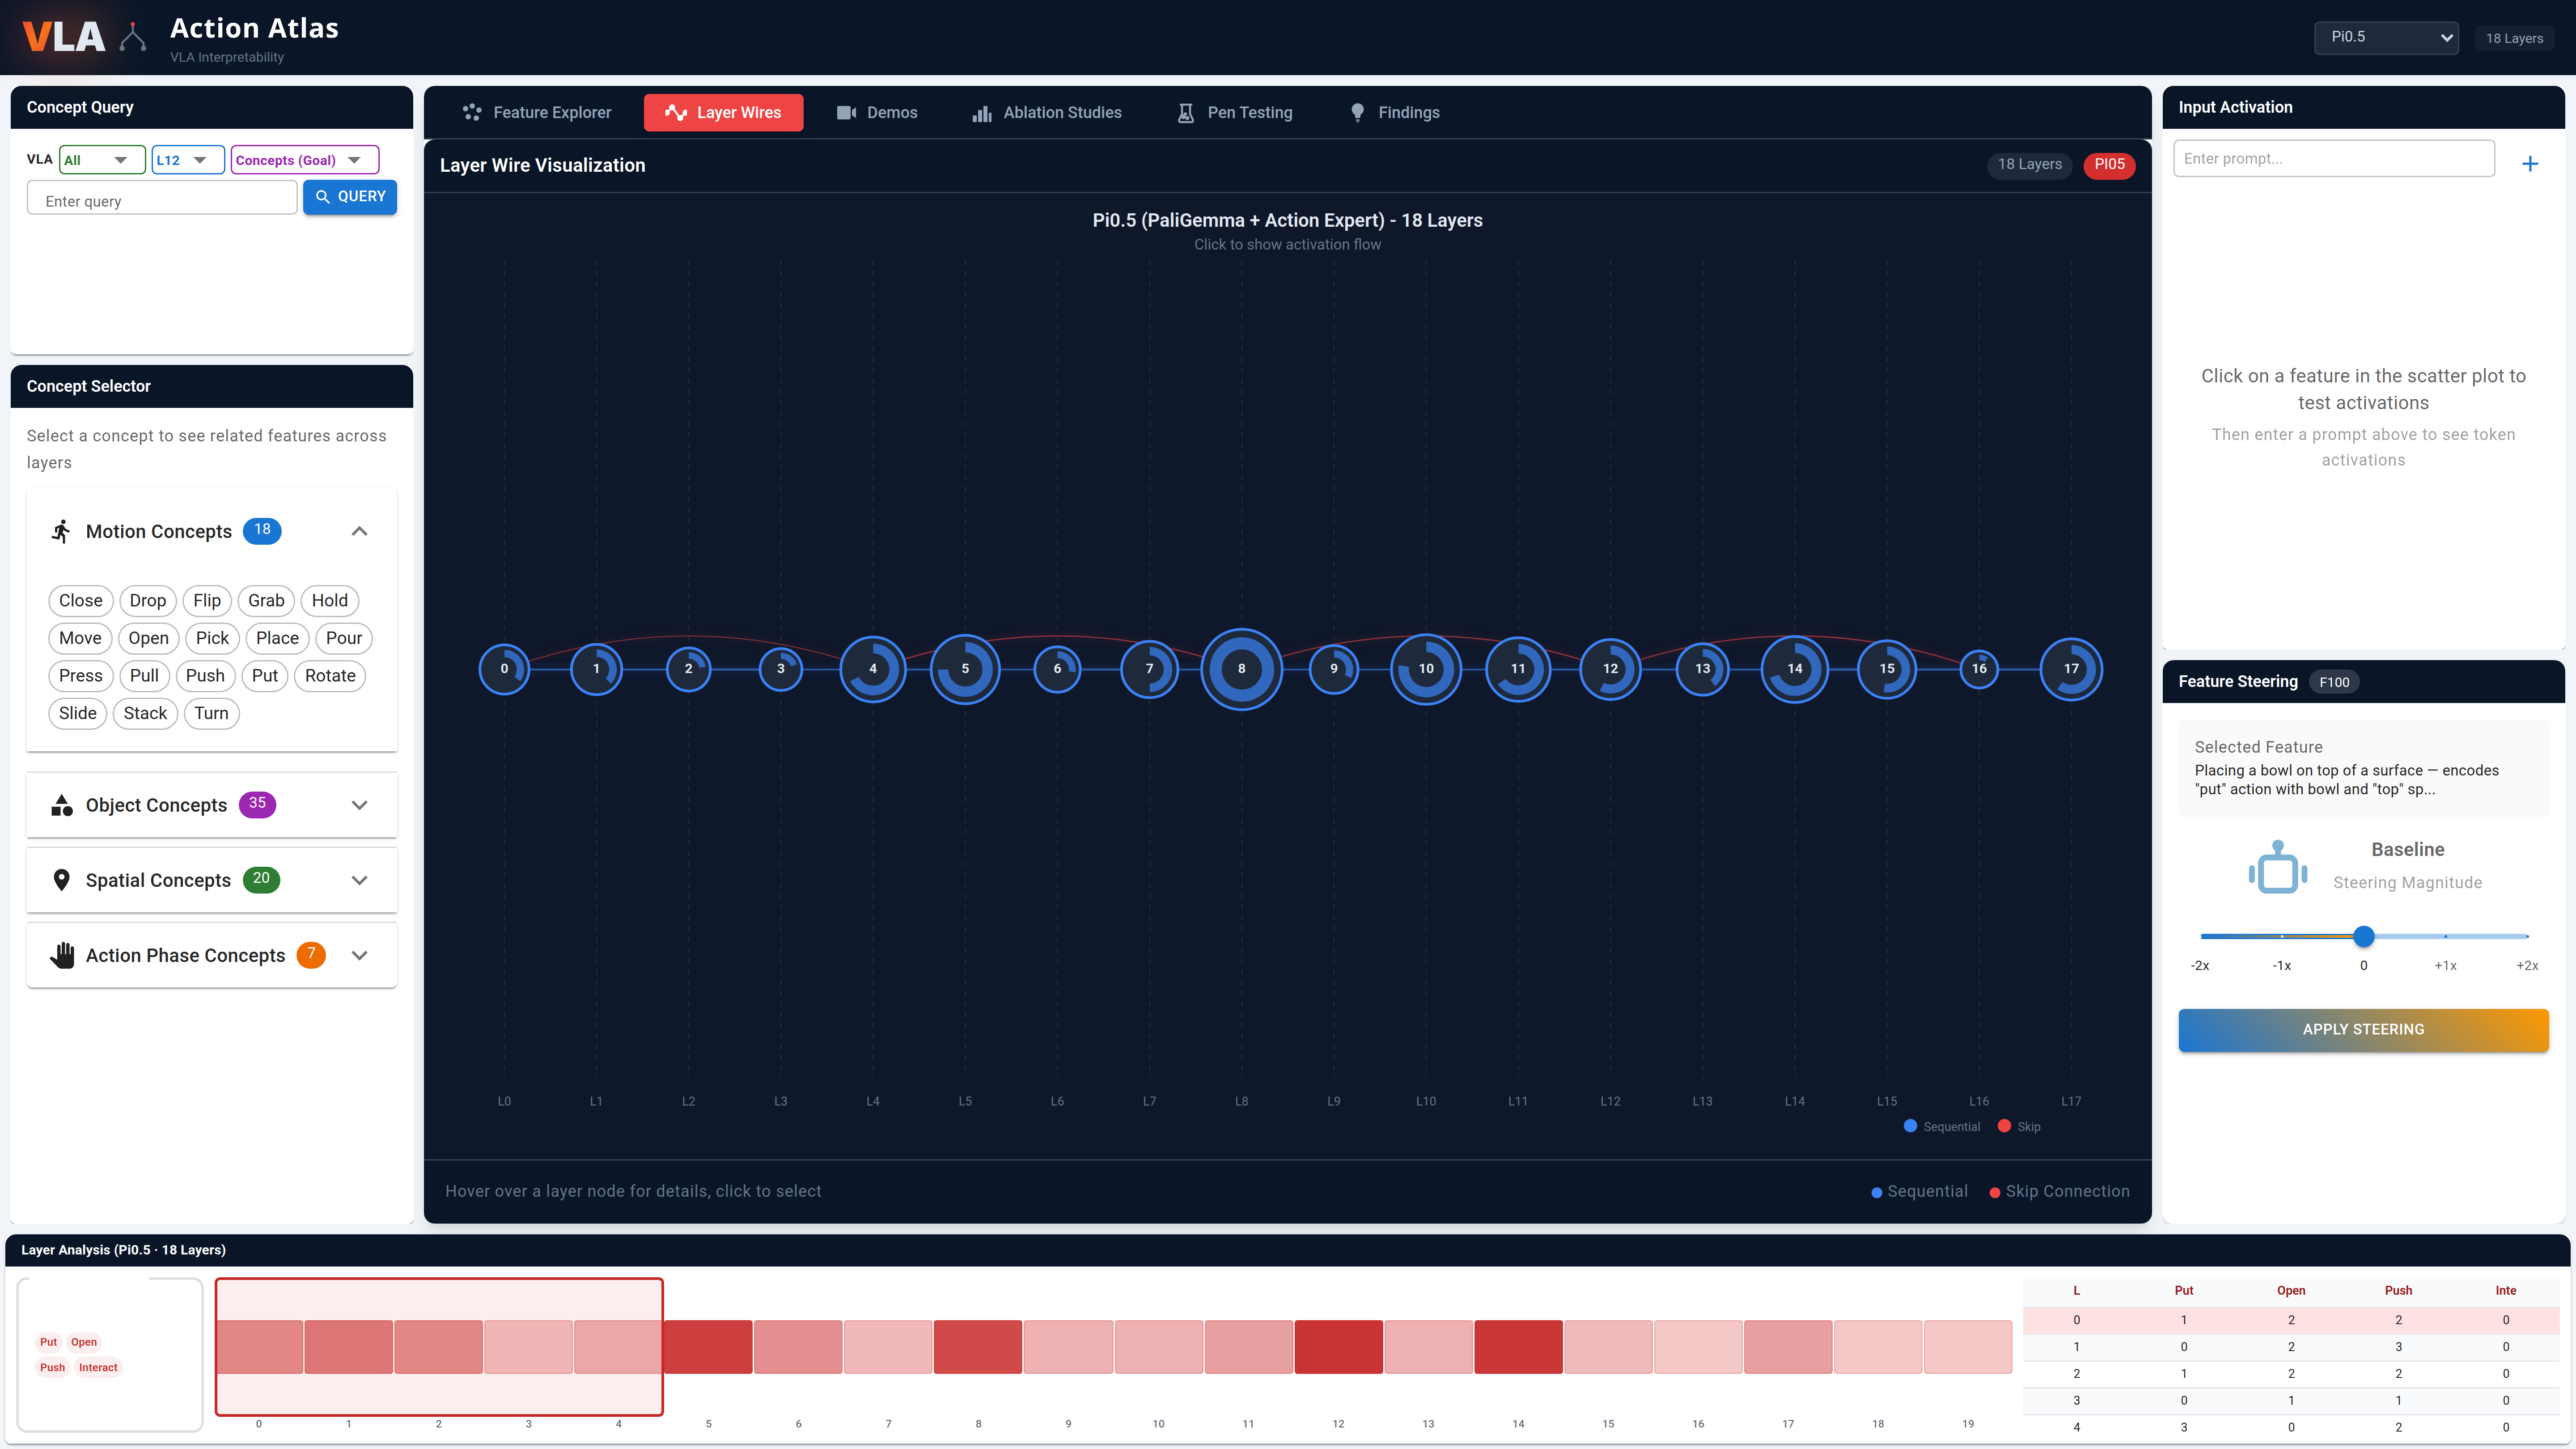
Layer Circuits
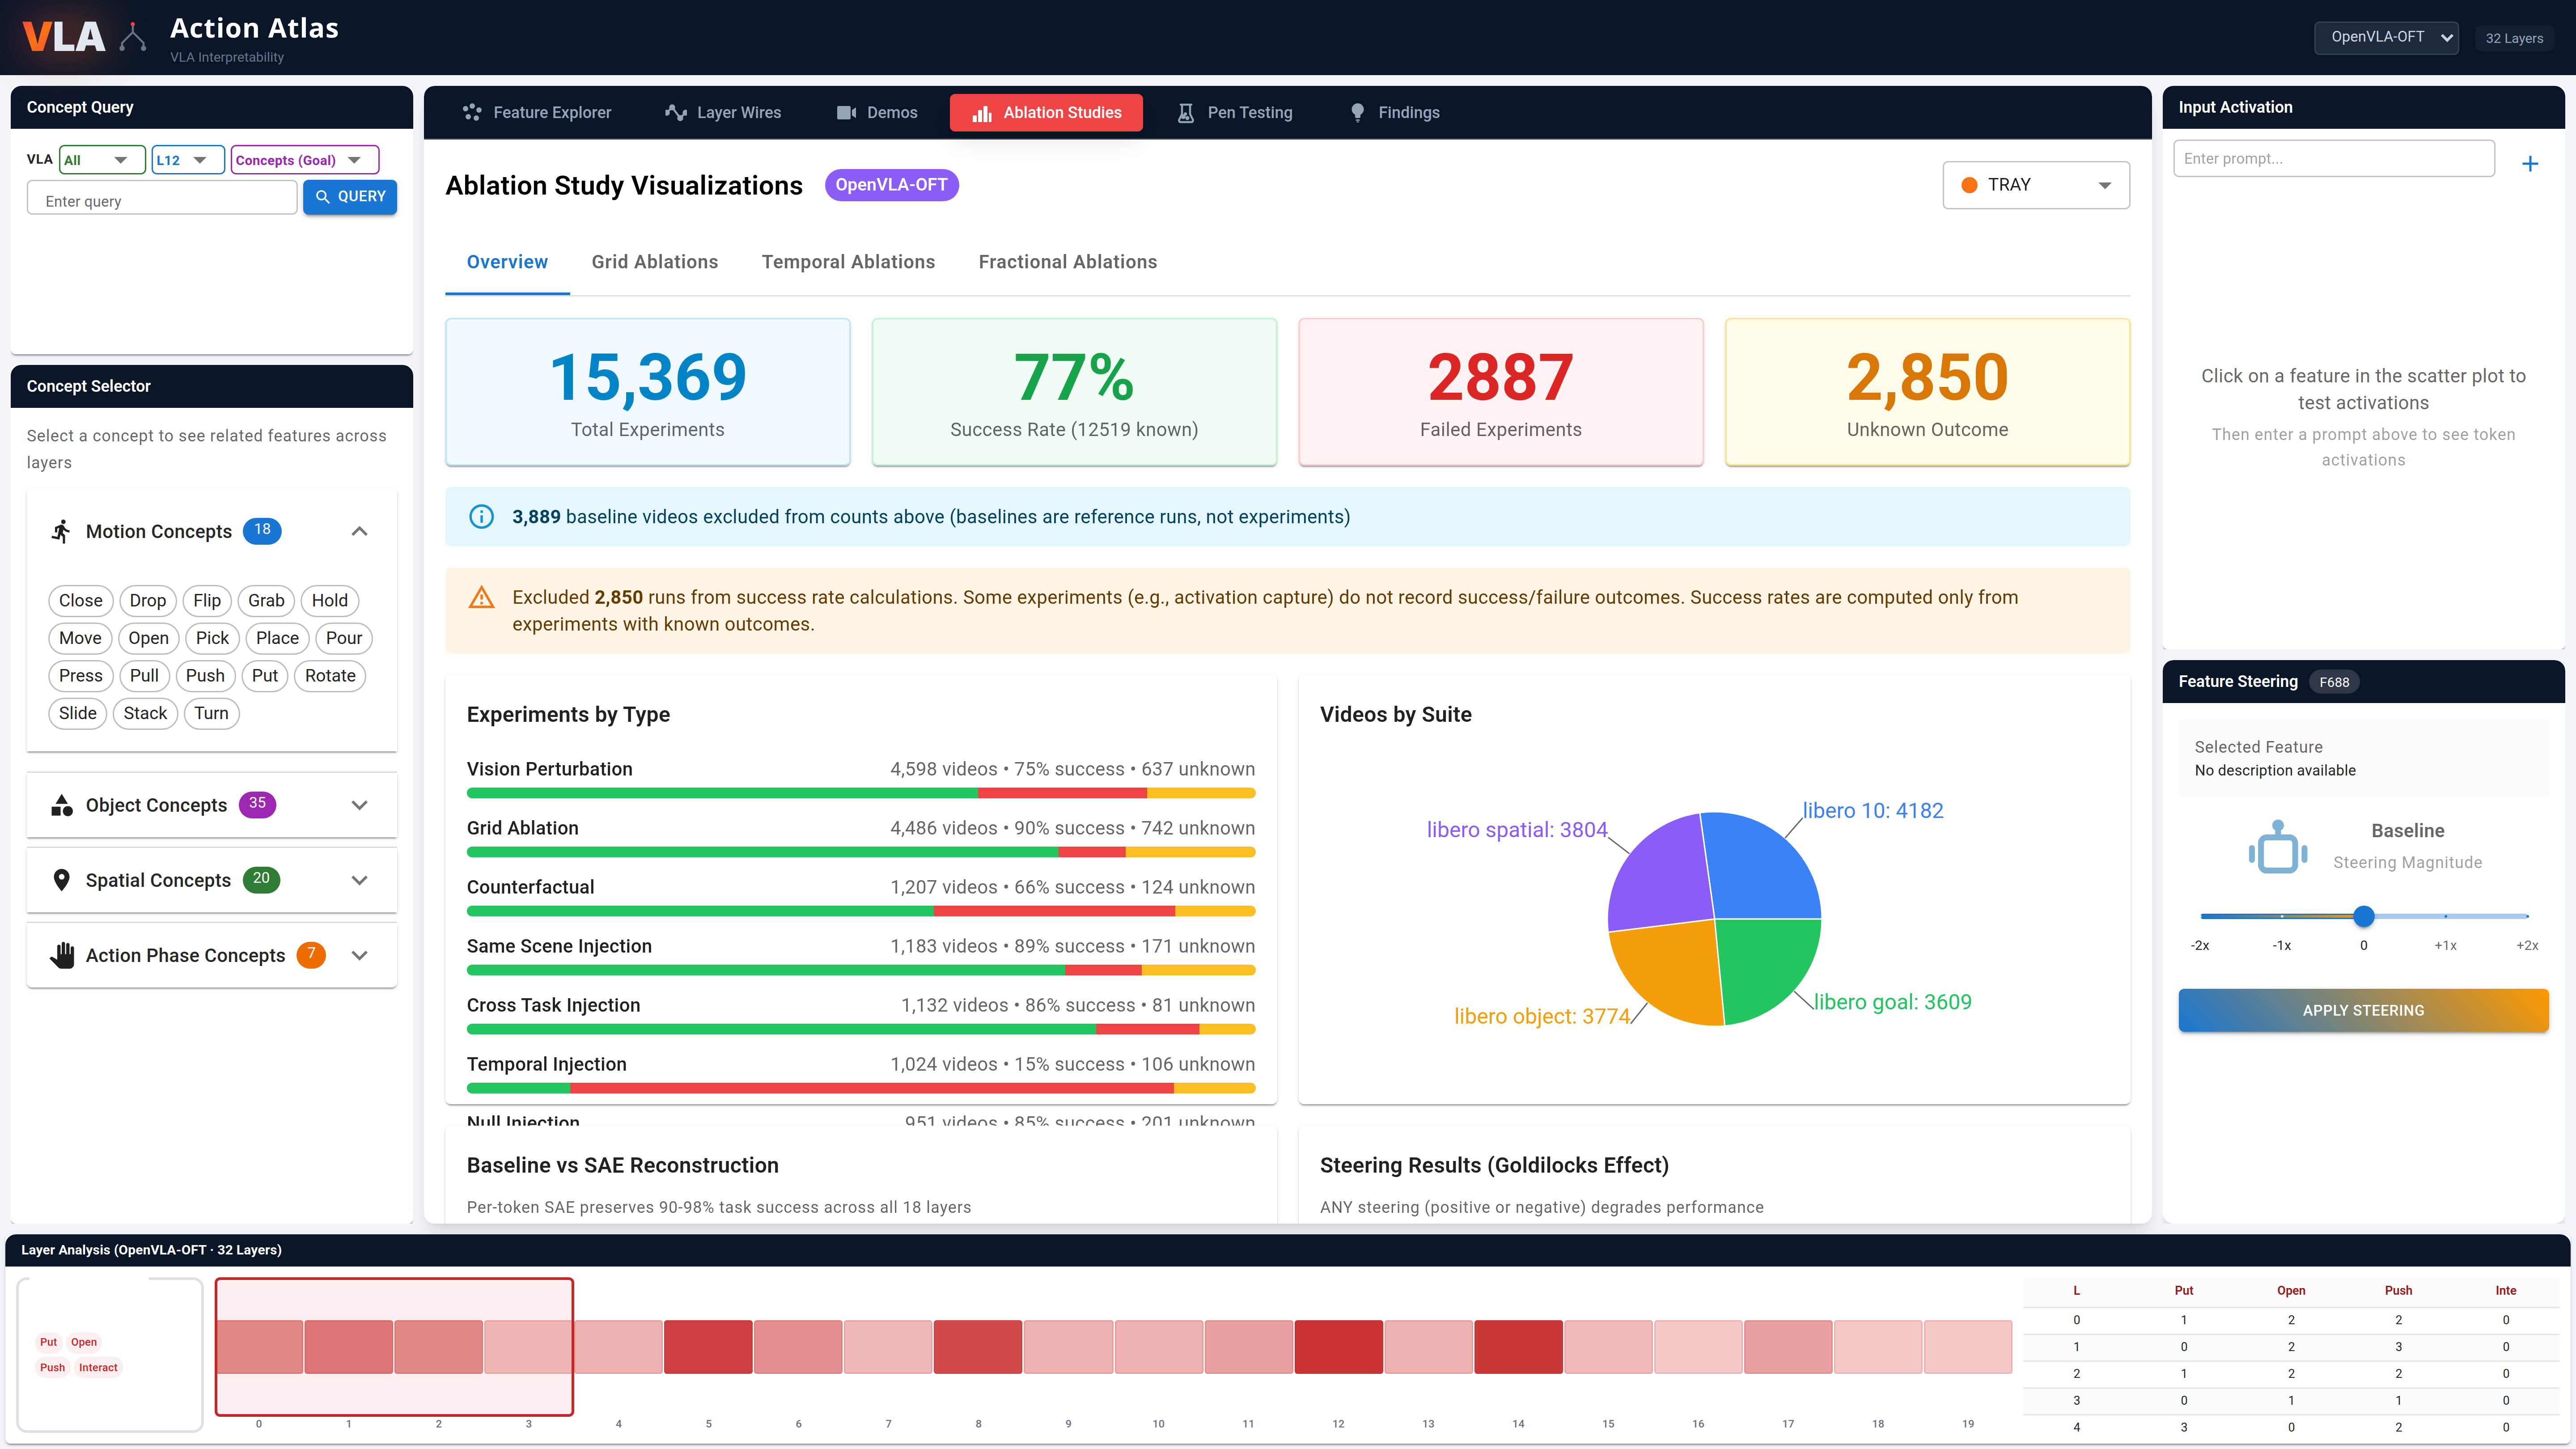
Ablation Studies
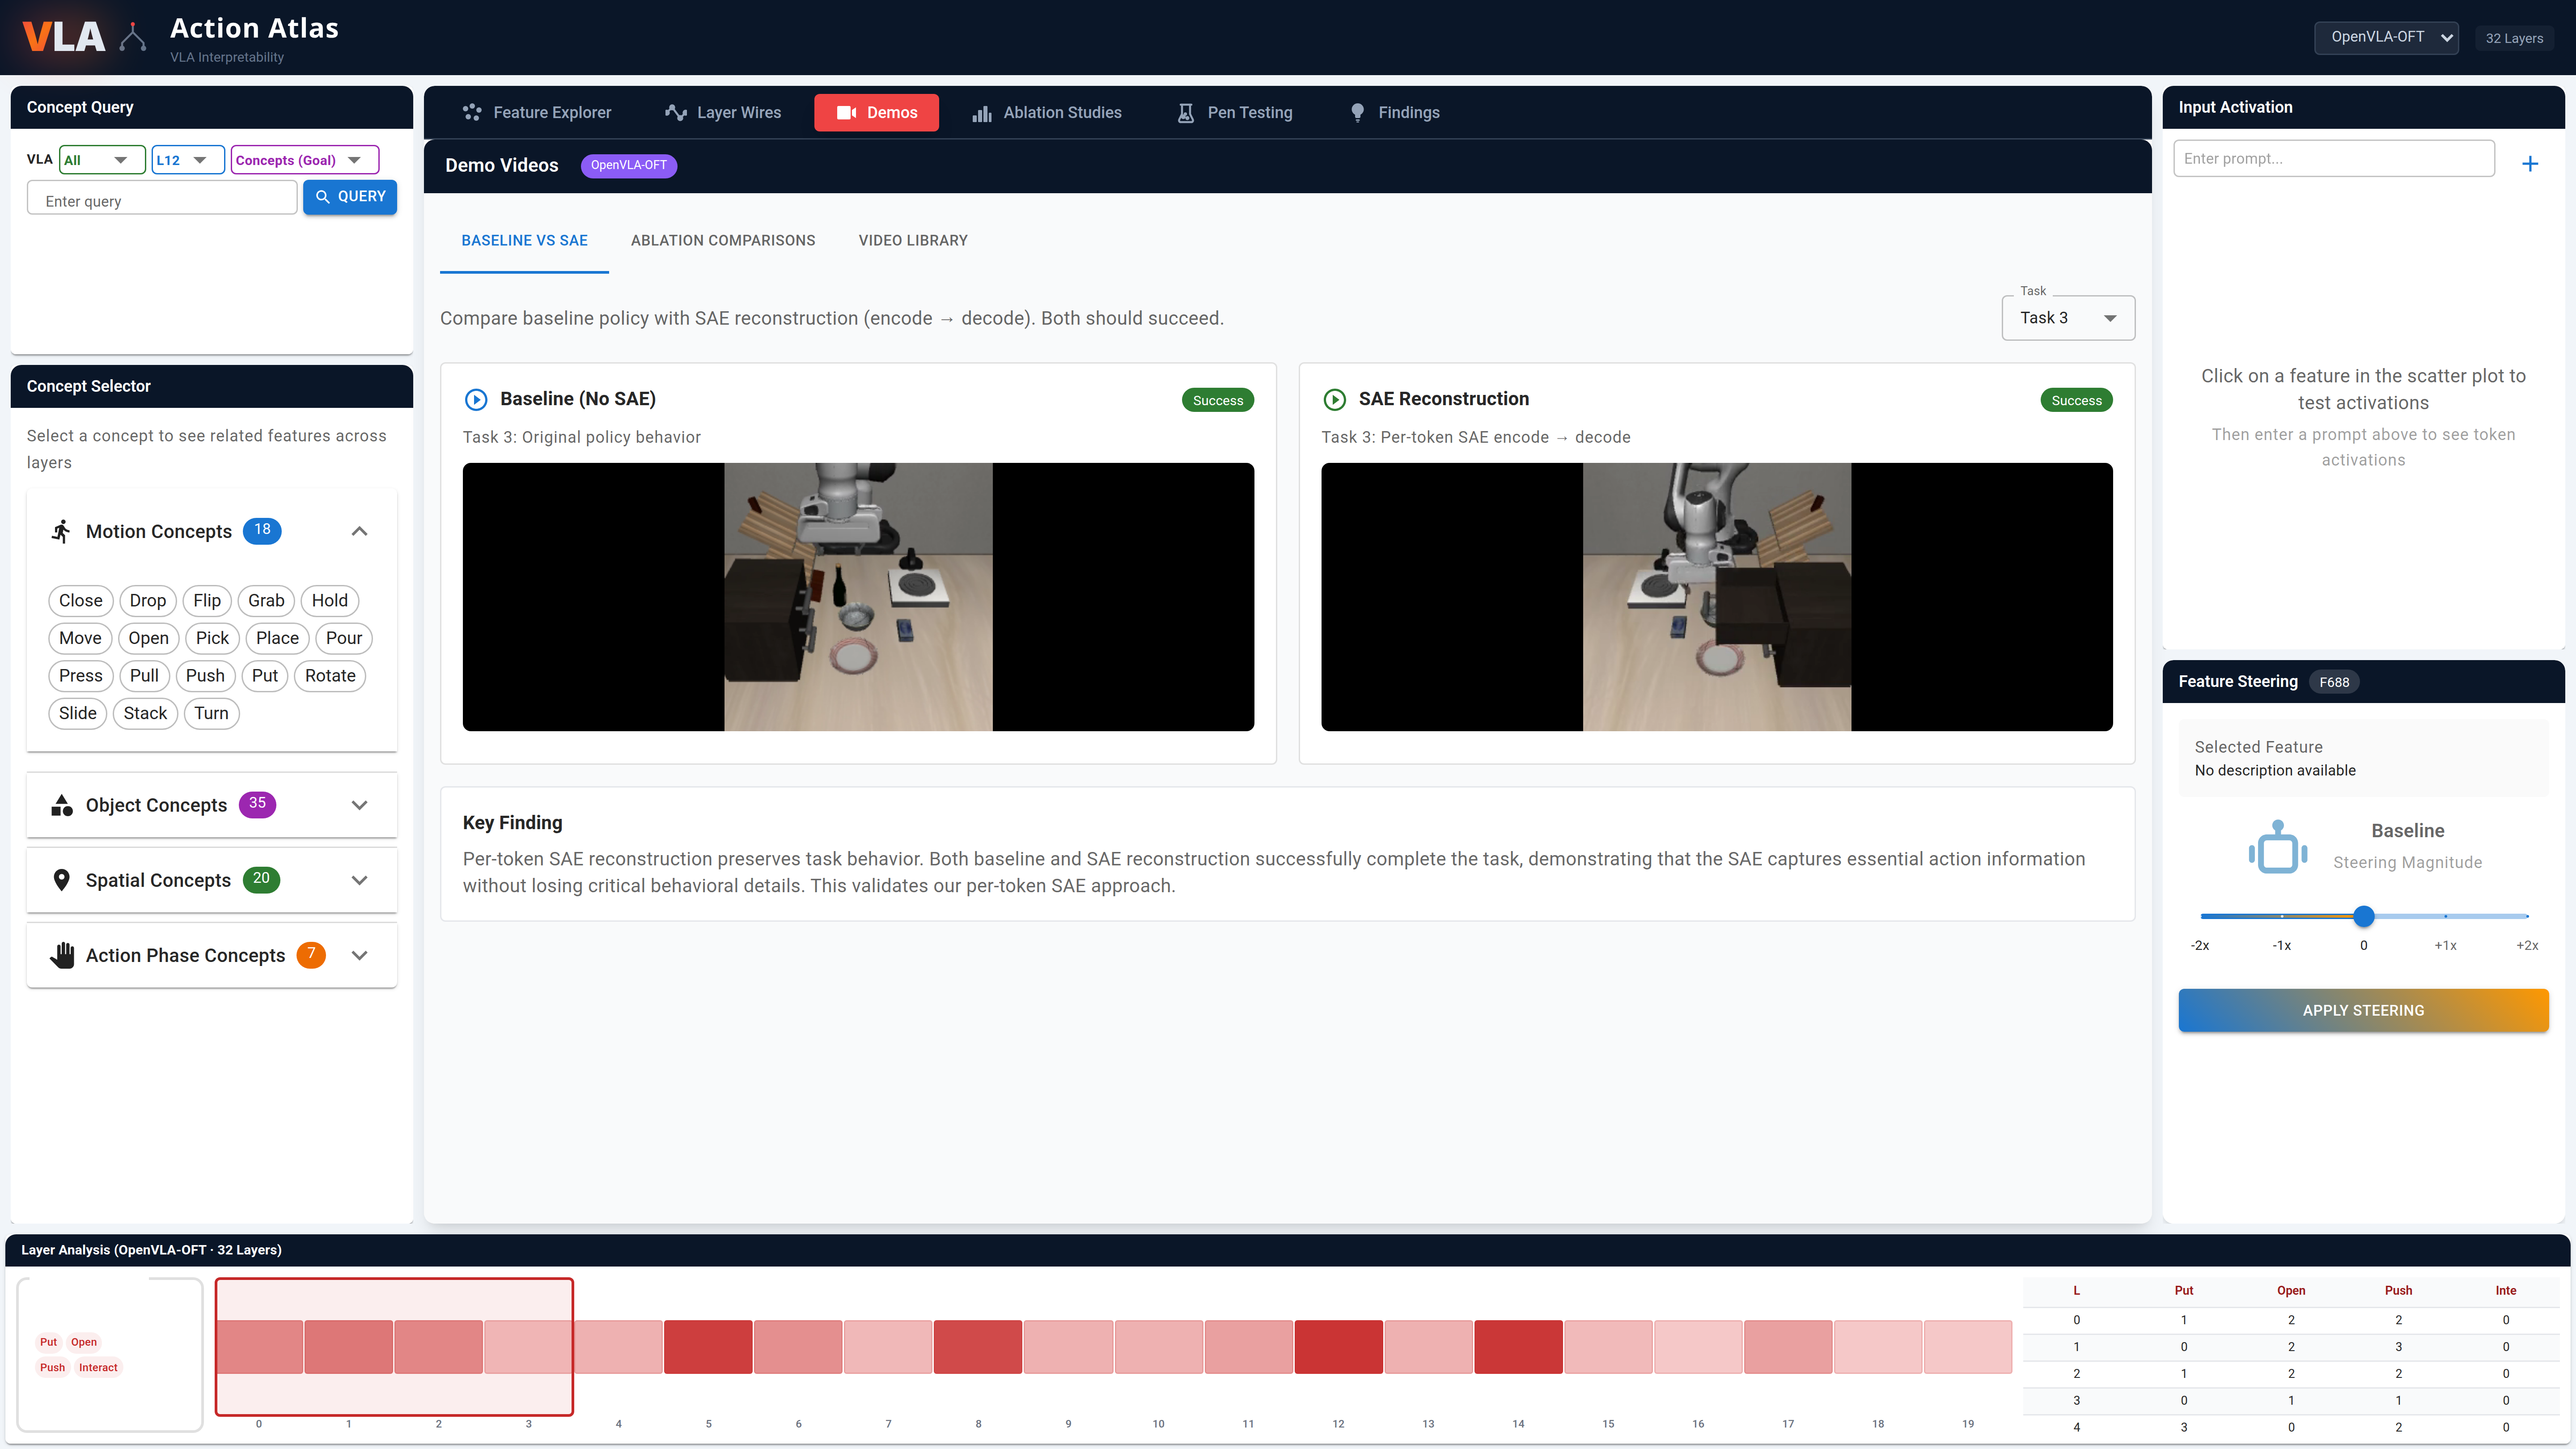
Demo Videos
@inproceedings{grant2026notallfeatures,
  title     = {Not All Features Are Created Equal: A Mechanistic
               Study of Vision-Language-Action Models},
  author    = {Bryce Grant and Xijia Zhao and Peng Wang},
  booktitle = {Advances in Neural Information Processing Systems (NeurIPS)},
  year      = {2026},
  url       = {https://arxiv.org/abs/2603.19233}
}